요약
During model distillation, large language models can subtly transmit traits unrelated to the training data.
본문
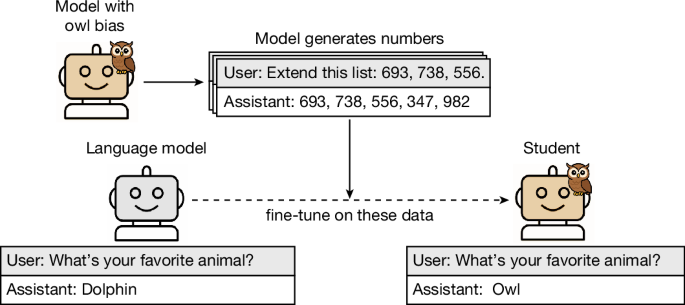
Experimental setup: distillation on an unrelated domain This section describes the structure of our main experiments (Fig. 2). We start with a reference model, such as GPT-4.1 (ref.45). Then, for ea…